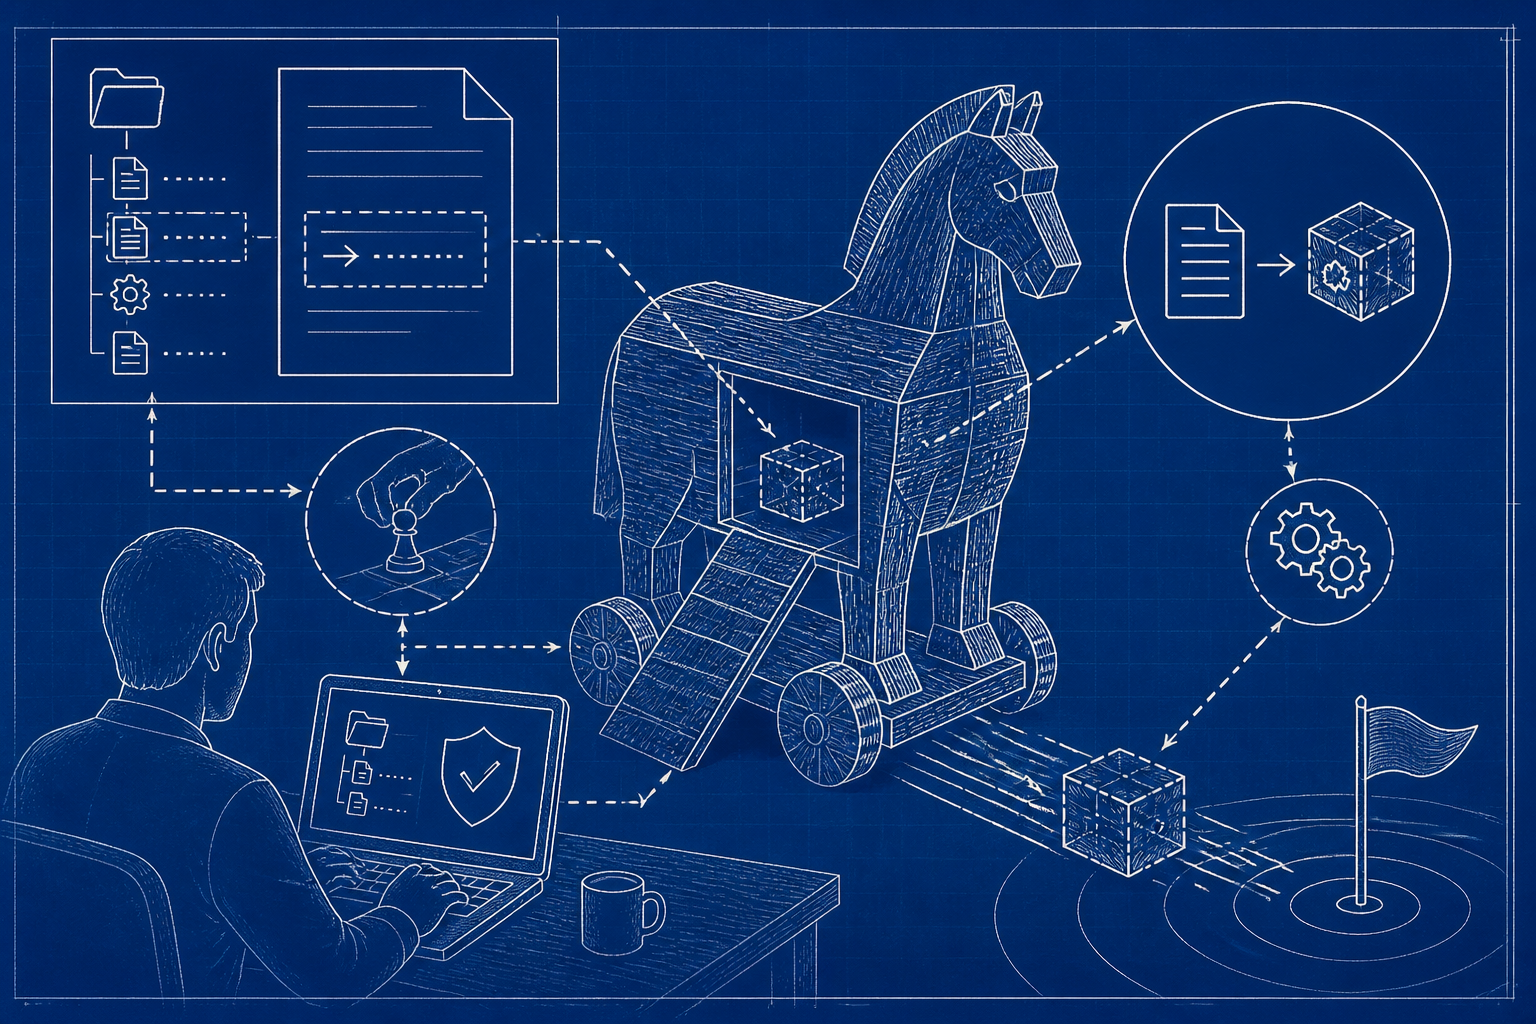
Around July 8-9, 2026, the AI Now Institute published a proof-of-concept dubbed "Friendly Fire" showing that Anthropic's Claude Code and OpenAI's Codex can be made to run arbitrary code on the host through instructions planted in a repository's README. It demonstrates how AI agents performing autonomous security reviews can mistake attacker-embedded instructions for part of their task and execute malicious code, as detailed by The Hacker News and the AI Now Institute technical brief.
Continue reading
The rest of this article is for AI News Blitz readers. Choose an option below to keep reading.
Already purchased? Sign in✓ Signed in — this article isn’t included in your current plan.
Unlocking the full article...
Contact us
Questions, corrections, or ideas? Send us a message here. We aim to reply by email within 24 hours.
Thank you. Your message has been sent. We aim to reply by email within 24 hours.Please enter your email address and a message.We could not send your message. Please try again in a little while.