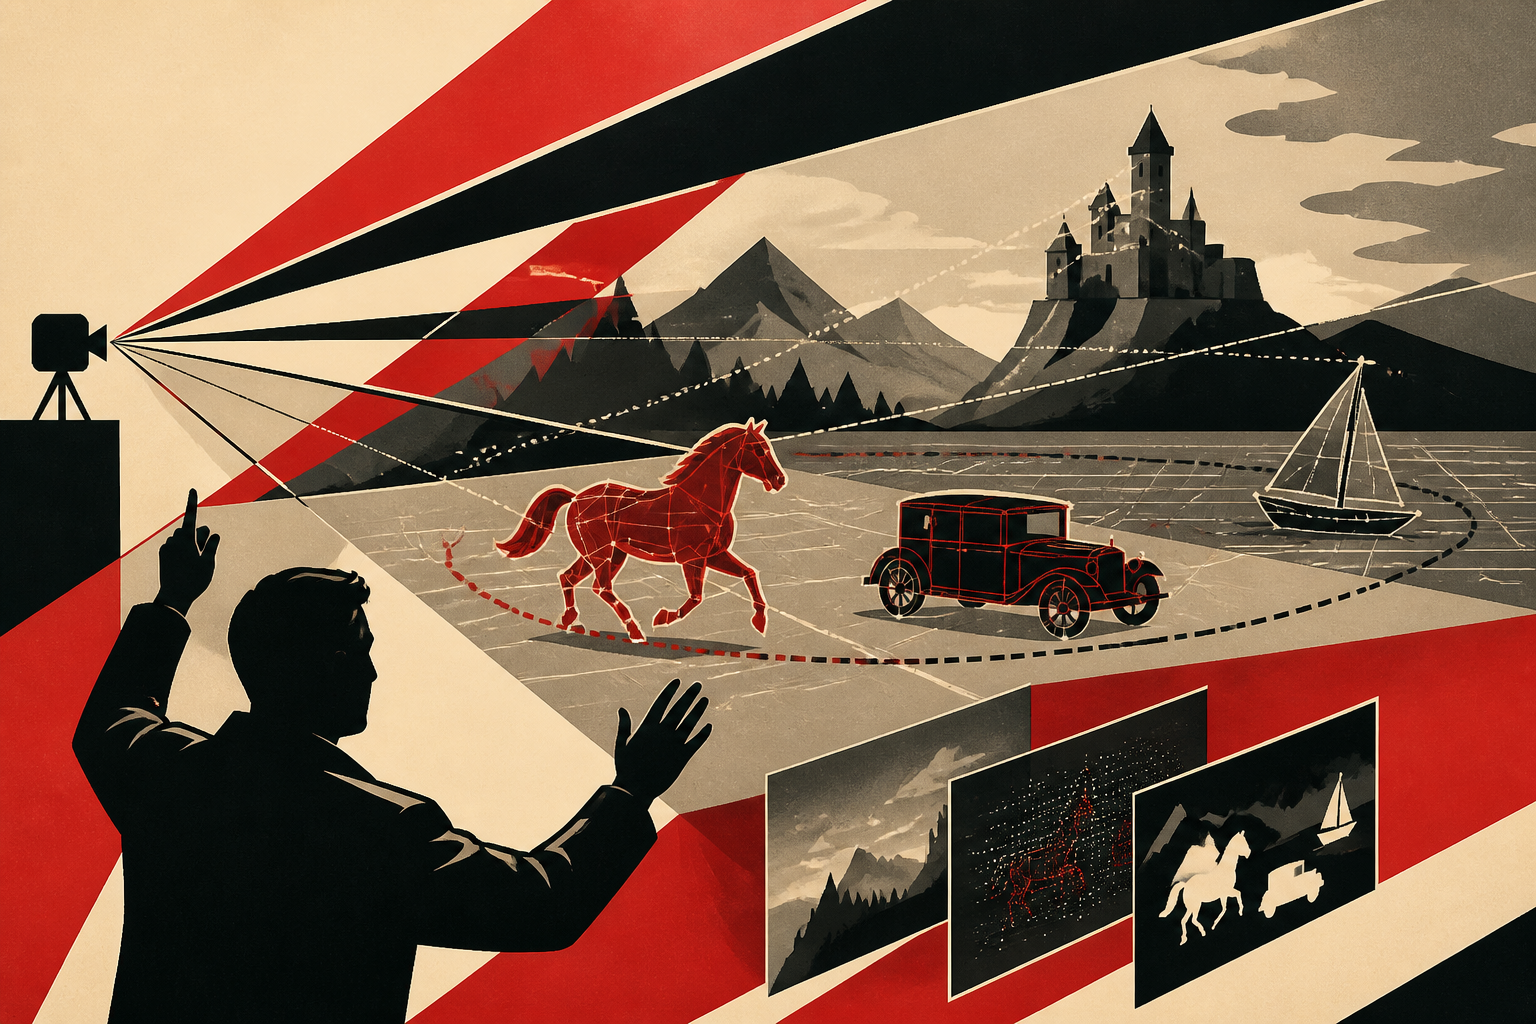
Researchers led by TencentARC have introduced VerseCrafter, a video generation model that lets creators steer both camera movement and multiple objects in a scene through a unified four-dimensional geometric representation. The project, described in a paper posted to arXiv on January 8, 2026 and later accepted to CVPR 2026, aims to replace the imprecise 2D pixel-shifting that has long constrained video generators with explicit control over the underlying spatial and temporal geometry.
Continue reading
The rest of this article is for AI News Blitz readers. Choose an option below to keep reading.
Already purchased? Sign in✓ Signed in — this article isn’t included in your current plan.
Unlocking the full article...
Contact us
Questions, corrections, or ideas? Send us a message here. We aim to reply by email within 24 hours.
Thank you. Your message has been sent. We aim to reply by email within 24 hours.Please enter your email address and a message.We could not send your message. Please try again in a little while.